Broadcom, OpenAI Ship Jalapeño Inference ASIC in Nine Months; Custom Chip Signals AI Vendor Vertical Integration
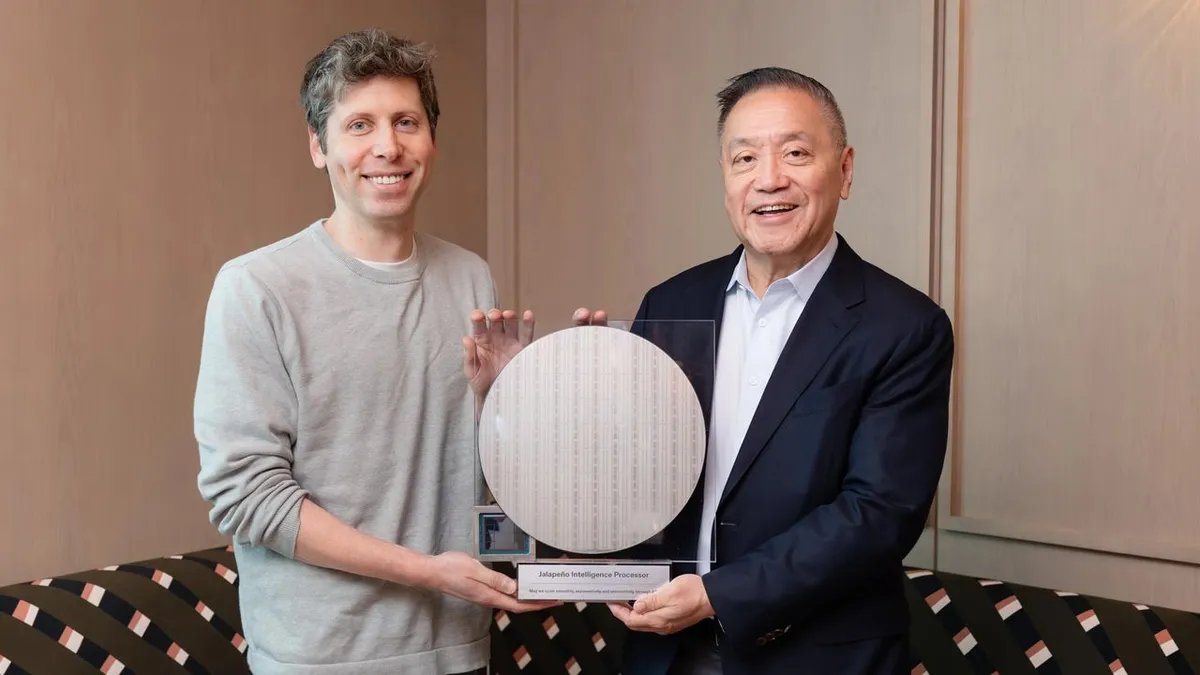
Broadcom's participation as foundry and co-developer is the leverage point. Broadcom now has direct access to frontier AI workload requirements and can commoditize inference silicon faster than Nvidia can defend its software stack. If Broadcom licenses Jalapeño derivatives to other cloud providers or AI labs, the inference ASIC becomes a platform — not a one-off.
That erodes Nvidia's ability to lock customers into H-series upgrades and forces a reckoning on software (CUDA parity, driver maturity) rather than raw compute. Second: OpenAI's vertical move exposes a gap in the current supply chain.
OpenAI is moving from customer to competitor in semiconductor design — a shift that forces Nvidia, AMD, and Intel to defend inference margins they've treated as secondary to training.
If Jalapeño delivers the claimed efficiency gains at scale, OpenAI captures the economics of its own inference workload and gains leverage over cloud providers who license its models. The nine-month timeline signals that custom silicon for AI inference is no longer a multi-year, high-risk bet; it's now a routine engineering problem that any well-funded AI company can solve.
Watch whether other frontier labs (Anthropic, Google DeepMind, xAI) announce similar programs within the next 12 months — if they do, the inference GPU market faces structural margin compression.
What is Jalapeño's actual performance-per-watt versus H100/H200 inference, and at what production volume does it become cost-competitive? The article cites claims but not independent benchmarks or pricing.
Fault Lines
Strategic intelligence, synthesized daily — with a public track record. Every call graded against what actually happened.